BeautyRAG
A hybrid search and RAG shopping assistant over an 8,000-product skincare catalog.
Runs on free-tier hosting (Supabase + Render). Supabase pauses the database after a period of inactivity, so if the demo errors out, that's almost certainly why — it needs to be resumed manually, not just revisited.
Context
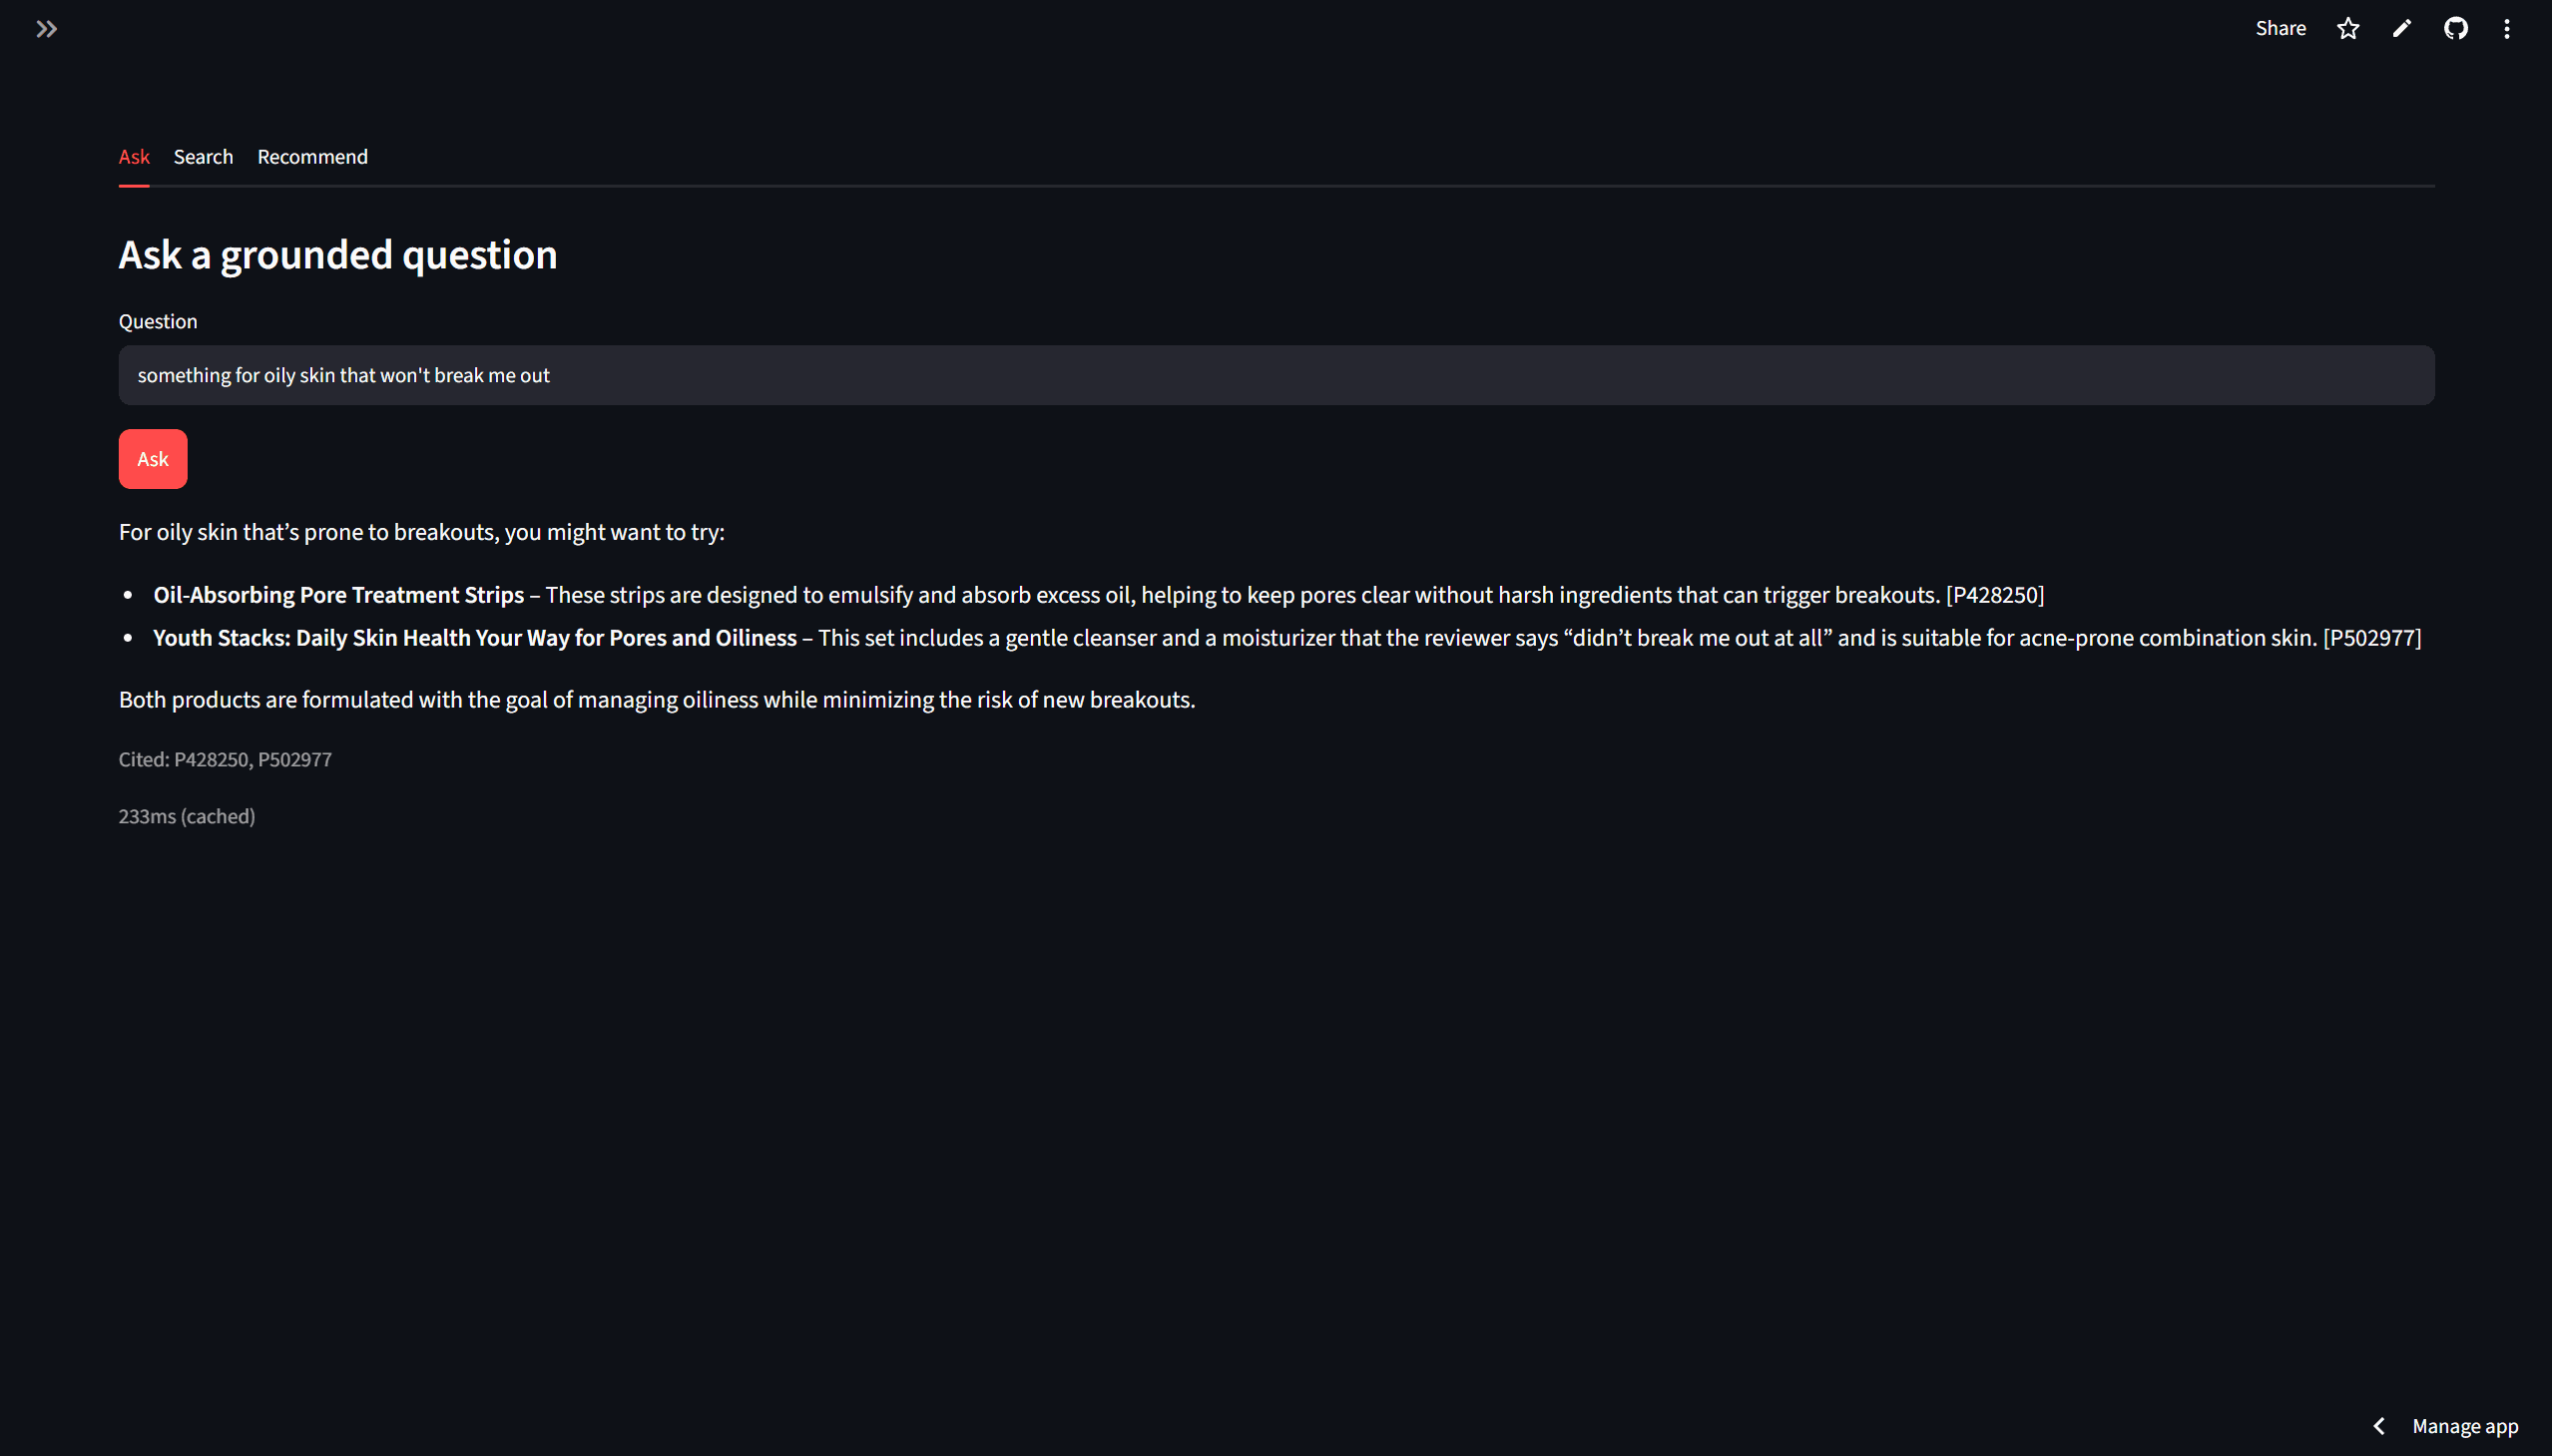
Skincare catalogs are large and the language people use to search them rarely matches product copy. Someone searching for "something for oily skin that won't break me out" is describing a need, not quoting an ingredient list, so keyword search alone tends to miss relevant products and pure semantic search tends to drift toward vaguely related ones. BeautyRAG was built to test whether combining both retrieval styles, and grounding an LLM's answers in the results, could do better than either alone across an 8,000-product catalog.
What it does
A shopper describes what they're looking for in plain language. BeautyRAG retrieves candidate products using two methods at once — PostgreSQL full-text search and pgvector cosine-similarity search — merges the two ranked lists with Reciprocal Rank Fusion, and hands the top results to a Groq-hosted LLM that writes a grounded recommendation. The assistant is restricted to talking about the retrieved products, so it can't recommend something that isn't actually in the catalog or invent claims about it.
Architecture
The FastAPI backend exposes a single async search endpoint that fans out to two retrieval paths in parallel: a PostgreSQL full-text query against product titles and descriptions, and a pgvector cosine-similarity lookup against sentence-transformer embeddings of the same fields. Reciprocal Rank Fusion combines the two ranked lists into one, and the fused top-k products are passed into the RAG prompt sent to Groq. Redis sits in front of the LLM call, keyed on the normalized query and retrieved product set, so repeated or similar questions return a cached answer instead of a fresh generation. A Streamlit front end talks to the API and renders the conversation. The whole stack is containerized with Docker.
Key technical decision + tradeoff
Results
- +13%
- Precision@5 vs. vector-only
- ~61ms
- p95 latency, cache hit
- ~54x
- speedup over uncached
Against a 12-query, human-labeled evaluation set, the hybrid RRF retrieval improved Precision@5 by 13% over vector-only search. On the generation side, Redis caching cut p95 response latency from roughly 3.3 seconds to about 61 milliseconds on a cache hit — a roughly 54x speedup. Retrieval quality was checked separately with a 20-query evaluation harness (Precision@5, Recall@5, MRR), where ground truth came from mechanically shortlisting SQL-filtered candidates and then labeling relevance by hand, rather than having the same model grade its own retrieval.
What's next
The evaluation set is still small — 12 to 20 labeled queries is enough to catch regressions but not enough to be confident about edge cases across an 8,000-product catalog. Growing that labeled set, and adding query rewriting for multi-turn conversations (right now each query is treated independently), are the two changes that would matter most next.